Agentic workflow · AgendaPro · 2026
An agent that sets itself up, and keeps learning after launch.
- Role
- Designed the process, the eight agents and the clinic-facing screens. Built the orchestrator.
- Users
- Clinic owners setting up their agent, and our implementation team.
- Scope
- Agentic workflow, human-in-the-loop, QA, interface design.
- Status
- Live. The process and the clinic-facing screens are in production.
The answers were already there.
The problem
Setting up an agent for a new clinic meant a long form and hours of calls.
Owners had to describe services, prices, team, rules and exceptions they had never written down. Most of it was already somewhere: in their calendar, on their website and in months of WhatsApp chats with patients. What they really knew, and we didn't, was a handful of decisions. So the question became: what if the agents read everything first, and the owner only answers what's left?
Time to deploy a clinic's agent
2–3→1
From two to three months with pairs of forward-deployed engineers, to one day with one person and an orchestrator agent.
It sets itself up.
From a connected WhatsApp to a first version the clinic can try, in a day.
What the owner sees · simplified from the product, with a made-up clinic
Building your agent
While it reads, the owner sees what it's reading. They can leave and come back: the questions wait for them.
What we need to know to finish Ema
Your team charged $25 for a physio session almost every time, but on 3 Oct it said $28. Which is right today?
Clinical topic
Pelvic floor after birth: does it need a doctor's referral before booking?
Each question shows what we found and where, the options, and what the agent will do if nobody answers. It saves itself, so a dropped connection loses nothing.
One orchestrator, eight sub-agents, four moments.
It starts when the clinic connects its WhatsApp. The agent it builds stays switched off until the owner has tried it.
The rules I designed it around.
Most of the design work was deciding what the agents should never decide on their own.
01
Don't ask what you can find out.
Every question is sorted: the agents answer it, they show what they found and ask for a yes, or they always ask.
02
History is a film, not a photo.
Recent chats weigh more. If a price changed in October, the owner sees both versions with their dates and picks one.
03
Clinical things are asked, never inferred.
Whether a treatment needs a referral is the clinic's call, not the model's.
04
Not answering never blocks the agent.
Every question says what happens by default. Usually: that conversation goes to your team.
It keeps training.
After launch, the clinic and its AI trainer keep improving the agent, with nobody from our team in between.
The loop
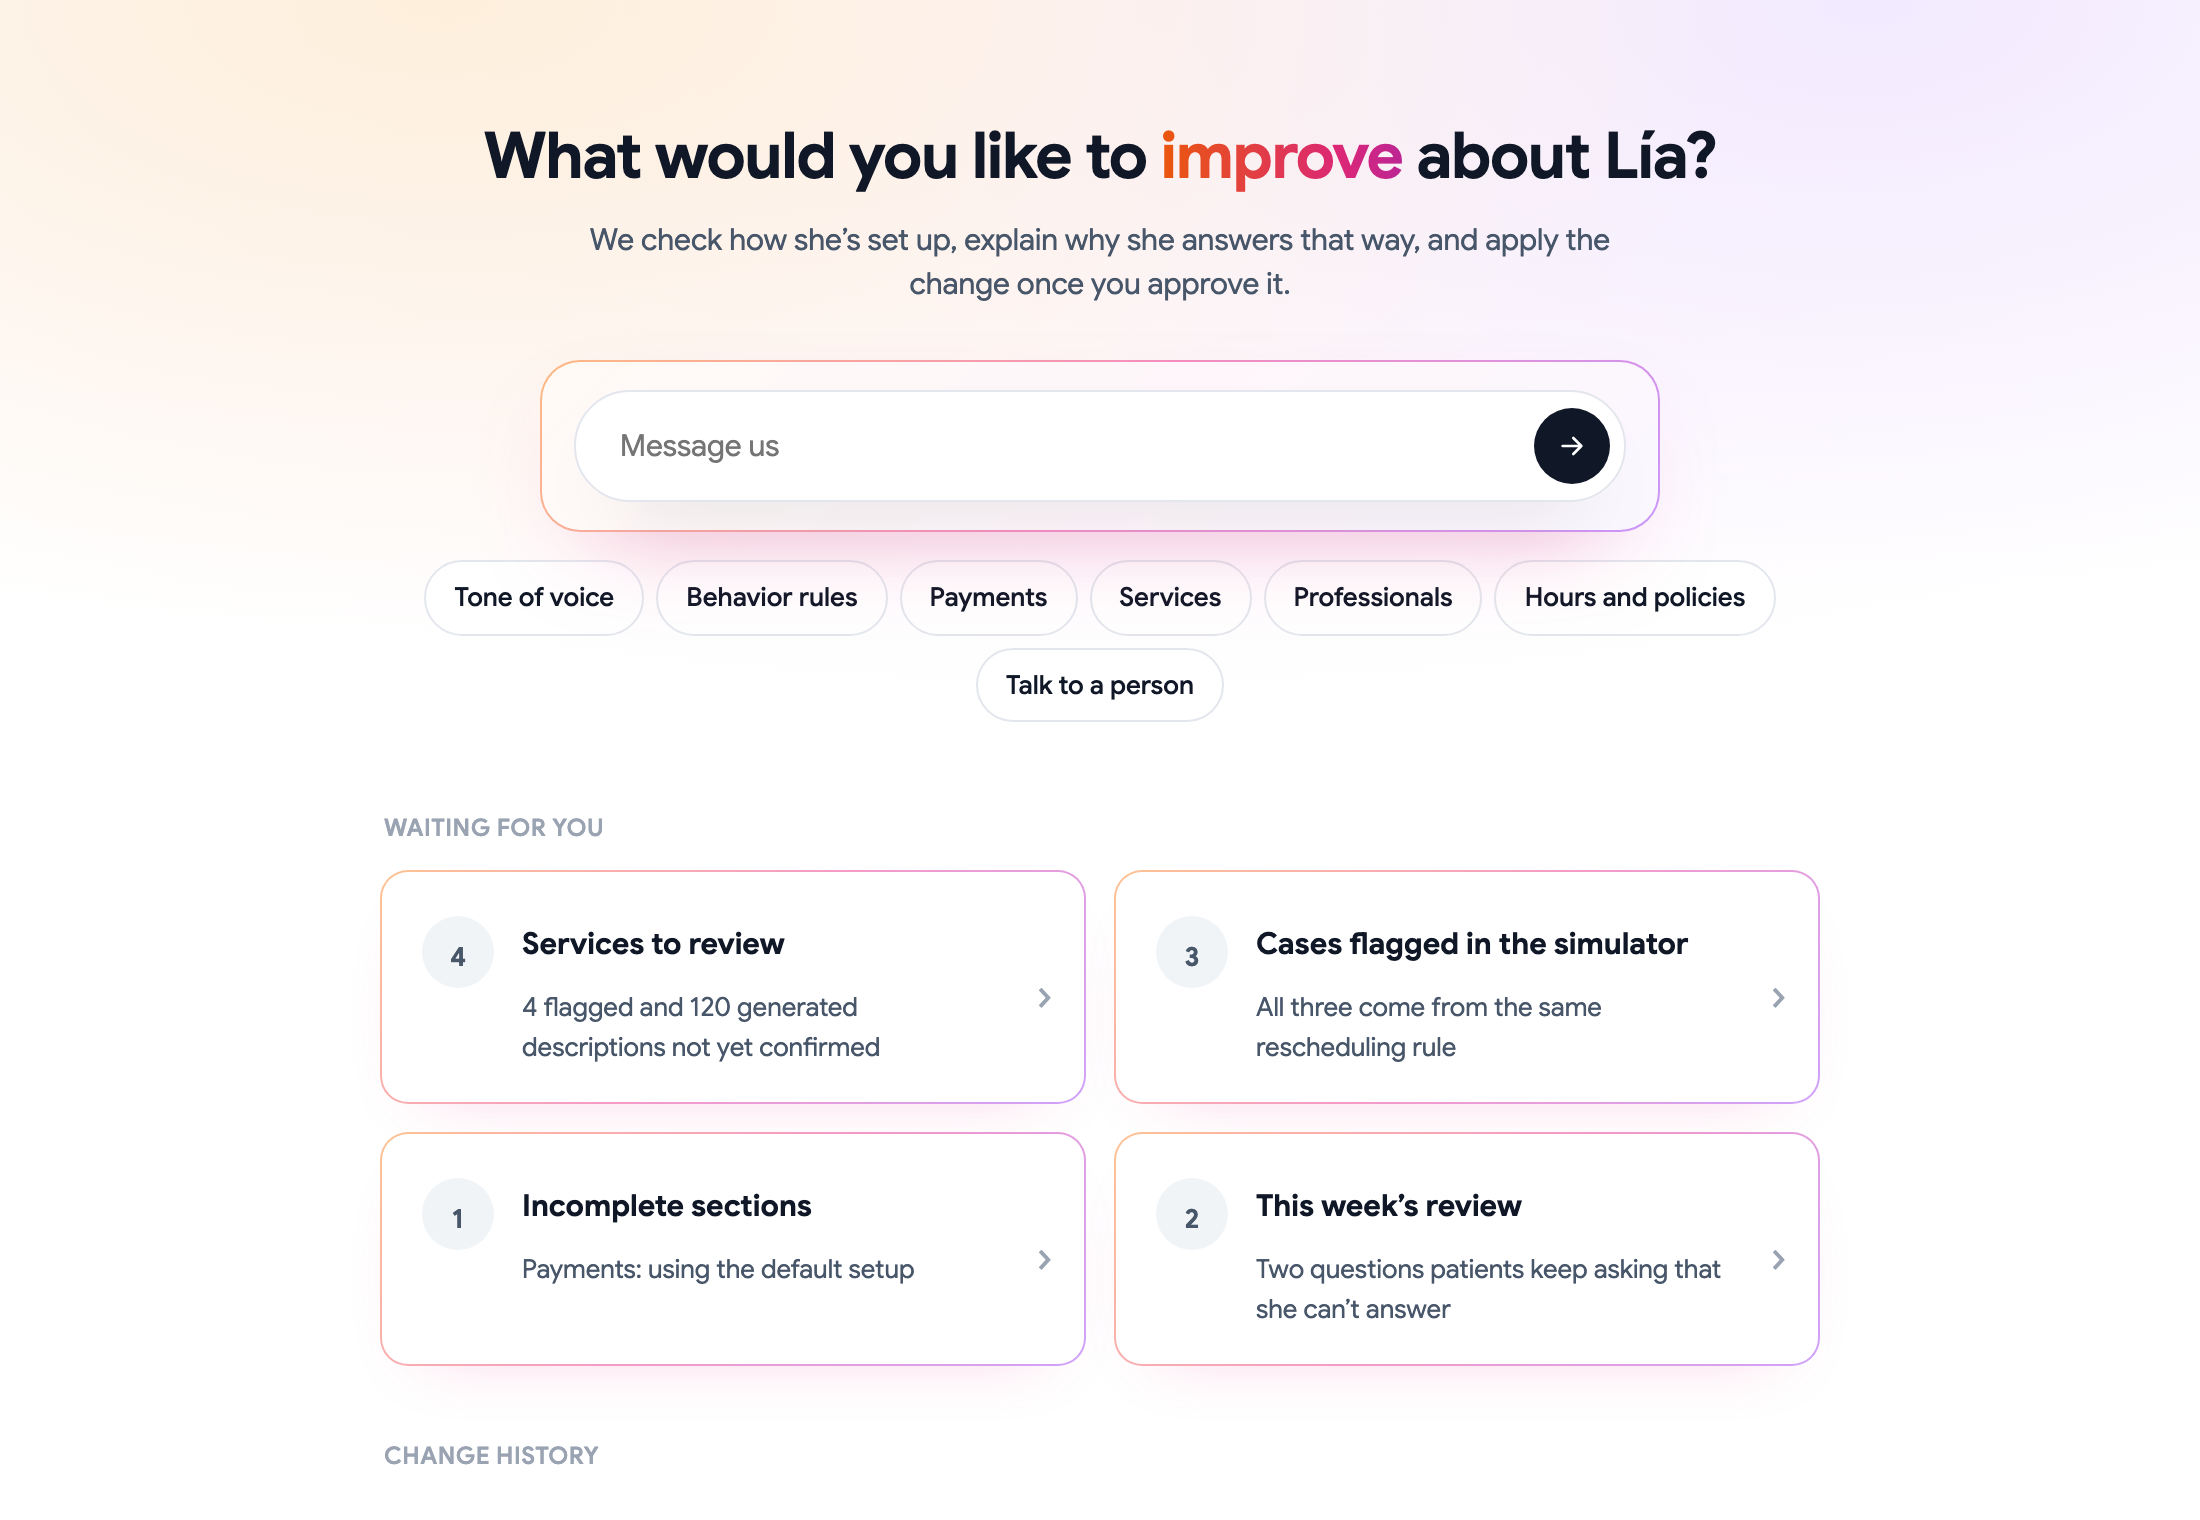
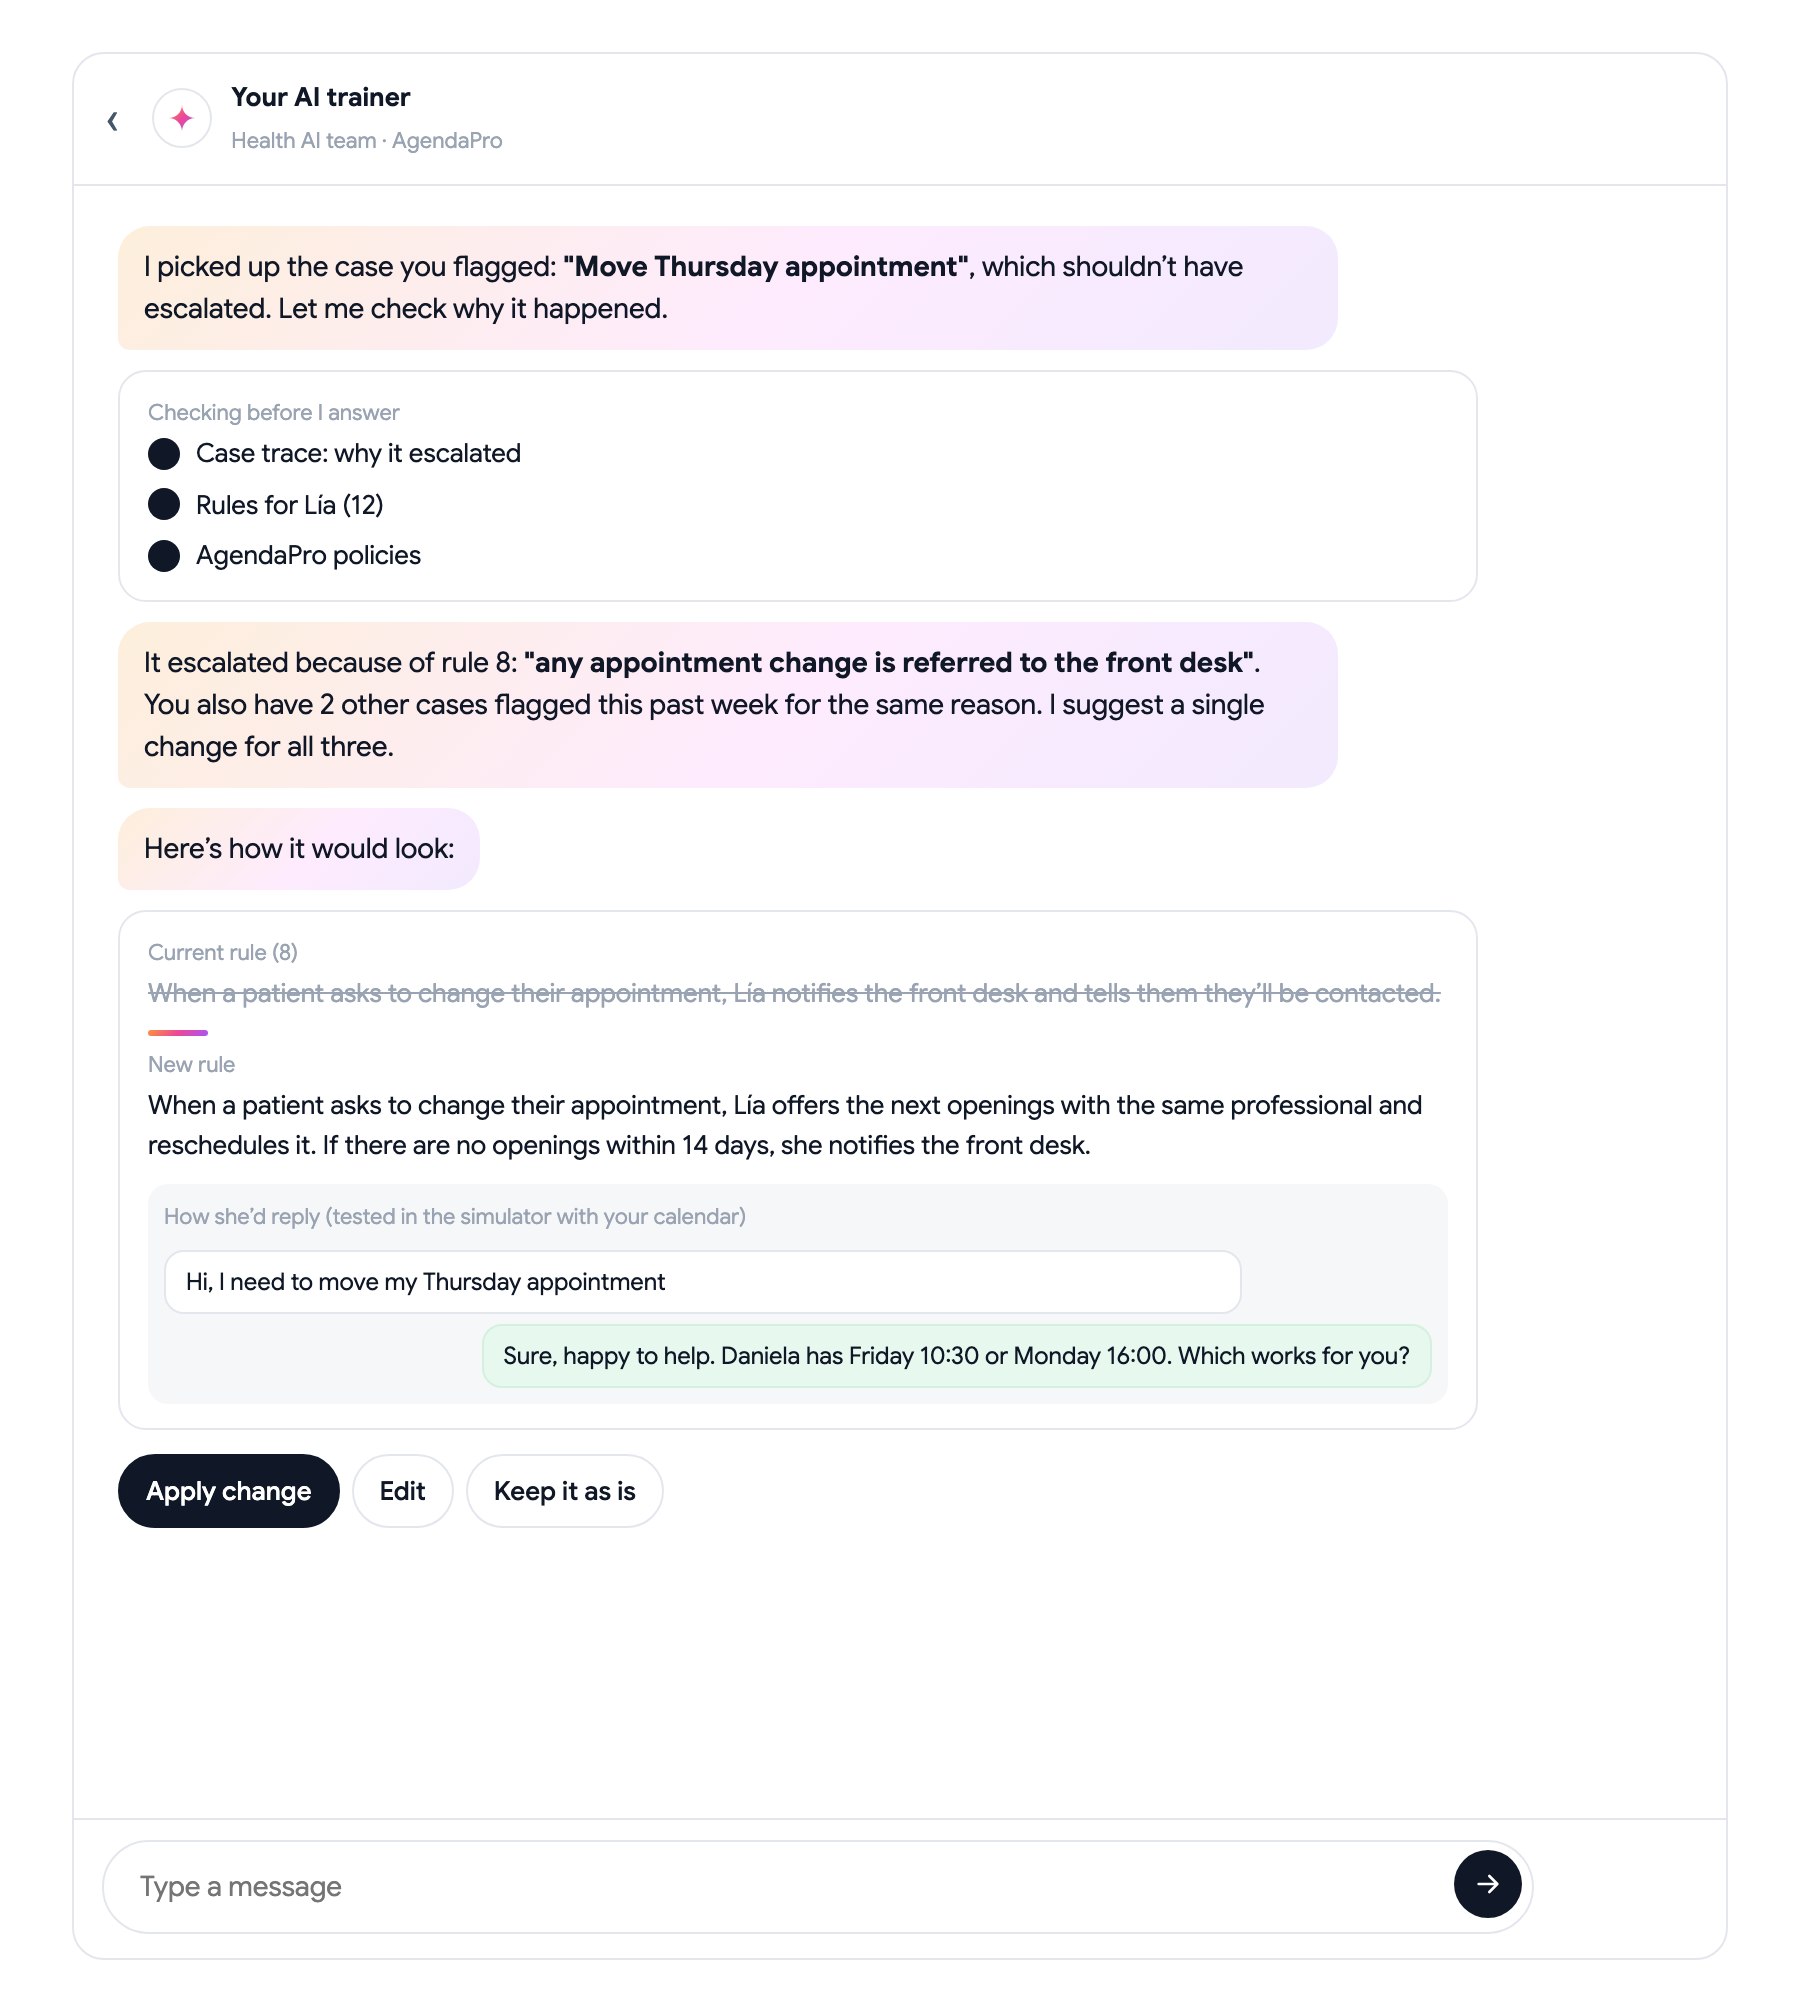
A flagged answer becomes a fix
It finds the rule behind the mistake, and shows the new answer before changing anything.
It reads the trace, groups similar cases into one change, tests it in the simulator with the clinic's real calendar, and waits for a yes. Every week it also brings back what patients asked that it couldn't answer.
Measured, not assumed.
Blind A/B tests with real patient questions, scored by a separate judge that didn't know which version was which.
Answer quality score, without and with each kind of knowledge
Real patient questions, answered in a sandbox. A separate AI judge, blind to the version, scored each answer on four criteria. Shown as % of the maximum score.
Light: without. Dark: with. 15 to 20 cases per test, one run per version. Country rules and short notes stayed; dental notes didn't, because they didn't help.
What it changed
- Country context stays. Without it, the agent said yes to an insurance plan that needed a voucher, and made up agreements.
- Long texts made things up more, so knowledge is short and only where a test shows it helps.
- For dental, extra text didn't help. So it isn't loaded.
The whole flow, in 30 seconds